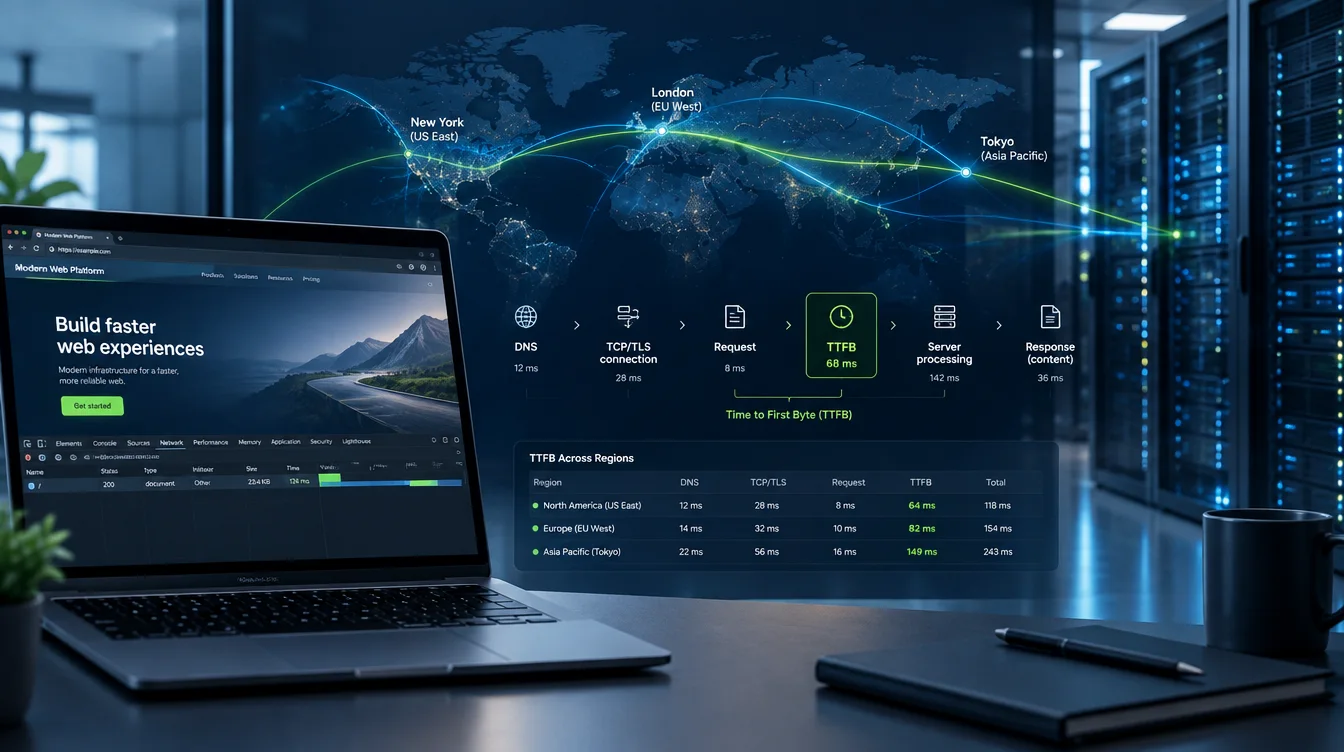
A page can feel slow long before anything renders. The browser starts a navigation and waits for the response to begin, and every later loading milestone is downstream of that wait. Time to First Byte describes the interval from navigation start until the first byte of the response begins to arrive. Once someone sees the number in a report, the next question is usually the same: what counts as a good TTFB?
There is a published guideline. It is also narrower than many comparisons make it sound, because a field distribution and a single controlled test answer different questions.
The published guideline is 800 milliseconds
Google's current web performance guidance describes a TTFB of 0.8 seconds or less as a rough guide for a good result, more than 1.8 seconds as poor, and the range in between as needing improvement. For a navigation request, TTFB can include redirects, service-worker startup where applicable, DNS lookup, connection and TLS negotiation, and the request time up to the arrival of the first response byte.
Two qualifications matter more than the number itself.
First, TTFB is not a Core Web Vital. The Core Web Vitals are Largest Contentful Paint, Interaction to Next Paint and Cumulative Layout Shift. TTFB is a diagnostic loading metric. It is not scored as a Core Web Vital, but a slow initial response can push later loading milestones such as FCP and LCP back because meaningful rendering cannot begin from document content that has not arrived.
Second, Google explicitly describes 0.8 seconds as a rough guide. A site does not have to chase the lowest possible TTFB in isolation if its delivery model still produces good user-centric results. A server-rendered page can have a somewhat higher TTFB yet still achieve a better FCP or LCP than a page that returns a shell immediately and then spends much longer fetching and rendering its meaningful content with JavaScript.
The field benchmark is not a verdict on one reading
Field performance is normally evaluated as a distribution across many real visits, with the 75th percentile commonly used for user-experience thresholds. A single laboratory run is one sample under one set of conditions. It cannot tell you the 75th percentile of your real visitors.
This distinction prevents a common misreading of TTFB. One controlled run returning 300 ms does not prove that most users experience a good TTFB, and one run returning 1.4 seconds does not prove that the site is broadly poor. TTFB can move between visits because DNS may or may not be cached, a connection may or may not be reusable, an edge cache may hit or miss, the origin may be under different load, and upstream routing or third-party dependencies may change.
The spread across repeated tests is often more informative than a single average.
Lab measurements and field data answer different questions
Field data comes from real visitors on real devices and networks. It tells you how a population actually experienced the site. A lab test is one controlled run from a defined environment. Both are useful, but they are not interchangeable.
A lab test is strongest when you use it for controlled comparisons. Run the same URL from the same Browser Node before and after a caching change and you reduce the number of variables, although cache state, routing, node conditions and third-party services can still introduce noise. Run the same URL from several regions and you can look for geographic patterns, while remembering that CDN routing, cache state and distributed backends may also differ by region.
Latixo is a lab measurement in this sense: it loads the submitted public page in a real Chromium browser from the selected Browser Node under a defined Desktop or simulated Mobile Test Profile.
The practical workflow is to set experience targets from field data when you have it, then use repeated lab tests to diagnose why those results look the way they do.
Distance sets a floor you cannot tune away
Before the server can return the document, the browser has to reach it. On a traditional cold TCP connection using TLS 1.3, with no reusable connection and no 0-RTT shortcut, connection establishment plus the first request and response involves multiple network round trips before application processing is fully reflected in the result.
That cost becomes visible over long distances. If round-trip latency is low, most of an 800 ms budget can remain available for server work. If round-trip latency is high, connection setup and request travel can consume a significant part of the budget before the origin's own processing time is considered.
This is why “what is a good TTFB?” should usually be paired with “measured from where?”. The same origin can look very different from a nearby region and from a distant continent without any code change. Serving cacheable HTML from an edge location closer to the visitor can reduce that network component because the response no longer has to make the full trip to a distant origin.
Repeat visits can differ again. When an existing connection is reused, some setup cost disappears. HTTP caching and edge-cache state can also change the path, which is one reason a later test may be noticeably faster than a cold run.
What the server is doing changes what good looks like
A single internal target across an entire site is rarely useful because different response types have different work to perform.
- Static HTML served from an edge cache. The document can often be returned with very little origin-side work. If response time is unexpectedly high, check whether the HTML is actually cacheable at the edge, whether the request is reaching the intended edge, and whether redirects or connection setup are dominating the run.
- Server-rendered pages with a warm full-page cache. These can also respond quickly, although revalidation, origin distance and cache misses can still add time.
- Uncached, personalized responses. Dashboards, carts, search results and other per-user pages may require session work, database queries and upstream API calls. Their realistic budget has to account for that backend work rather than assuming the same target as cached HTML.
- Redirect chains. Redirects are part of navigation TTFB and can add extra network work, especially when a redirect changes host and requires additional DNS or connection setup. Remove unnecessary hops and collapse redirect rules at the server or edge where possible.
Lighthouse's 600 ms number is a different measurement
The older Lighthouse “Reduce server response times” audit used 600 ms as its failure threshold for the main document's server response. Chrome's documentation also explains that this server-response measurement is only part of full navigation TTFB and excludes some work such as DNS and redirect time.
As of Lighthouse 13, that audit has moved into the Document request latency insight. The useful lesson is not to force the old 600 ms Lighthouse number and the 800 ms TTFB guideline to agree. First identify exactly what the tool on screen measured.
Setting a benchmark you can use
A workable approach for most sites is to start with field data when it is available, examine the distribution rather than only the mean, and then separate targets by response type. Cached documents and personalized responses should not automatically share one budget.
Geography should be part of the target when you serve more than one region. A single global average can hide the exact regional problem you are trying to diagnose.
From there, use lab tests for comparisons that can produce actionable evidence: the same URL before and after a caching change, the same URL from multiple Browser Nodes, or a cached route against a comparable uncached route. Repeat the tests so that a small one-off fluctuation is not mistaken for a real improvement.
Your own history is also a useful benchmark. A consistent improvement for the audience and regions that matter to the site is meaningful even when the final number does not match a generic table perfectly.
Checking TTFB from the regions you serve
Latixo currently provides eight selectable LIVE Chromium test locations: Virginia, Seattle, Nuremberg, Tokyo, Singapore, São Paulo, Beijing and Sydney. Each run uses the Browser Node selected for that test.
For the Website Speed Test, Latixo reports TTFB together with the current production test's document/load and request-level observations where supported, plus a WebP screenshot and WebM Loading Replay. Tests can be run with the Desktop or simulated Mobile Test Profile.
Because each run is a single lab sample, compare the same URL more than once and, when geography matters, from more than one region. A regional difference is evidence to investigate network distance, CDN or cache behavior, DNS answers, routing and region-specific backend behavior; TTFB alone does not cleanly separate all of those components.
The website speed test metrics guide explains how to read Latixo's measured timings and why one Browser Node should not be treated as a representative sample of every visitor in that country.
Practical rule: treat a TTFB result as evidence, not a verdict. The useful goal is a response fast enough that the initial document is no longer the reason later user-visible loading milestones are late for the people and regions you actually serve.