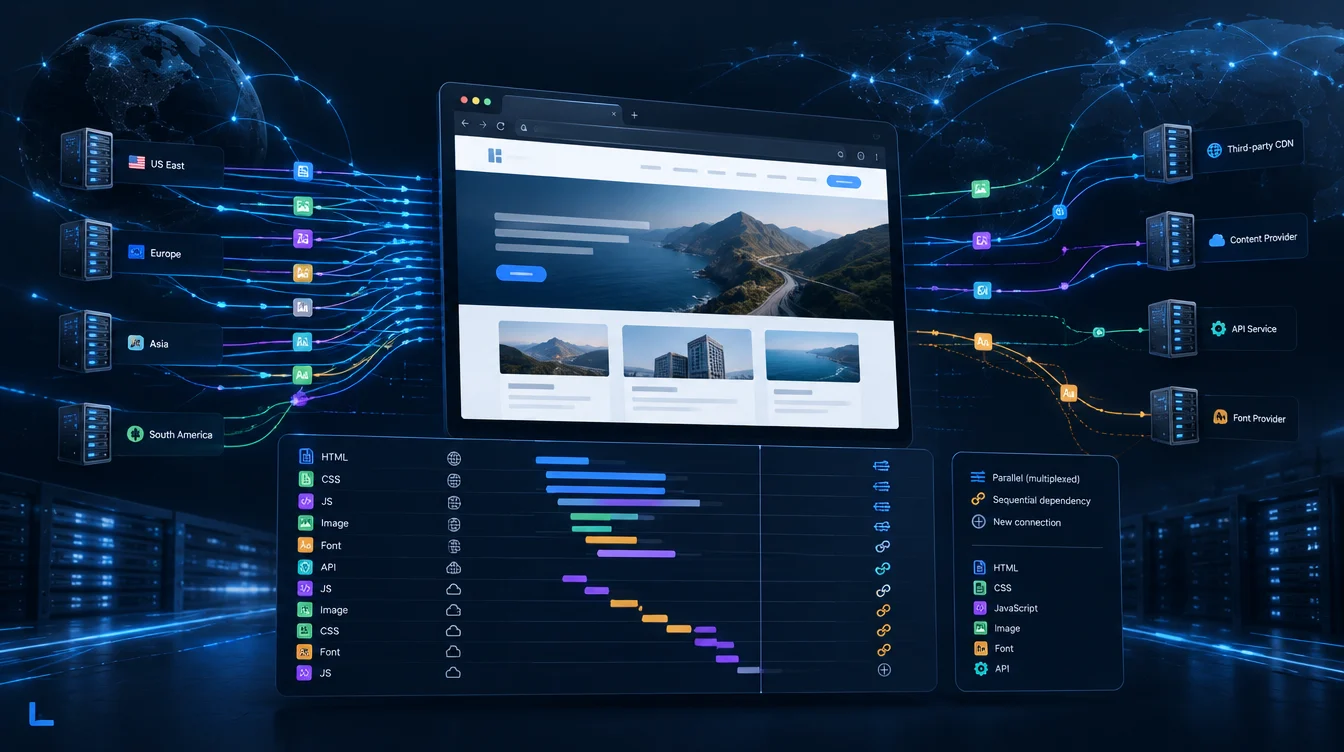
Sometimes, but the count on its own tells you little. Each request costs something: bytes, possibly a new connection, sometimes server work, and often JavaScript the browser has to run. How much that adds up to depends on what the requests are, where they go, and when the page needs them. A page with 120 requests can render faster than one with 40 if those 40 form long dependency chains across several third-party origins.
The advice to “make fewer HTTP requests” came from a time when requests themselves were often a major bottleneck. On modern protocols, the more useful question is which requests stand between the visitor and a usable page.
This guide covers what a request costs today, why request depth usually matters more than request count, when adding requests can help, and how to read the request count in a Latixo speed test without over-reading it.
Where did “reduce HTTP requests” come from?
The advice is older than most of the sites it gets applied to. With HTTP/1.1, requests on an individual connection are effectively serialized in normal browser use, so browsers open several parallel connections to the same origin to keep resources moving. Modern browsers have commonly used about six parallel HTTP/1.1 connections per origin.
A page that needs dozens of files can therefore create queueing when more resources are waiting than the available connections can carry.
Front-end developers built a set of techniques around that constraint. They merged CSS into one file and JavaScript into another, packed icons into image sprites, inlined small images as data URIs, and spread assets across multiple hostnames to gain additional parallel connections through “domain sharding.” Under HTTP/1.1, those techniques could reduce request queueing.
HTTP/2 changed the constraint. It allows many request and response streams to share a connection and compresses repeated header fields. HTTP/3 keeps multiplexed streams but moves HTTP onto QUIC, which changes connection establishment and avoids TCP's connection-wide delivery blocking between independent streams.
Some old techniques can now work against you. Domain sharding can force additional DNS resolution and connection setup and can split traffic across connections unnecessarily. Browsers may sometimes coalesce eligible connections, but that is not a reason to design around domain sharding. Large sprites and giant bundles also mean that a small change can invalidate a much larger cached file. The rule of thumb outlived many of the conditions that originally made it useful.
What does an extra request actually cost today?
A request is not a fixed unit of delay. Its cost depends on what the browser and server have to do to satisfy it.
New connection
Significant when: the request goes to an origin the page has not contacted yet, especially across a high-latency path.
Small when: the browser can reuse an existing HTTP/2 or HTTP/3 connection.
Round-trip latency
Significant when: the request cannot start until an earlier response arrives, creating a dependency chain.
Small when: the browser discovers it early and fetches it in parallel with other resources.
Transferred bytes
Significant when: the response contains large images, video, uncompressed text, or heavy JavaScript.
Small when: the asset is small, compressed and cacheable.
Bandwidth contention
Significant when: a slow or congested connection has many downloads competing with critical resources.
Small when: the connection has enough spare capacity and the critical resources are prioritized effectively.
Main-thread work
Significant when: the response is JavaScript that must be parsed, compiled and executed, or CSS that causes substantial style and layout work.
Small when: the resource does not create significant work on the critical rendering path.
Server work
Significant when: the request triggers an uncached dynamic response such as an API call, personalized fragment or application endpoint.
Small when: a static asset can be served quickly from an appropriate cache or CDN.
Nearly all the variation in “request cost” comes from those differences. Ten small image thumbnails from your own CDN over an existing multiplexed connection can be cheap. One tag-manager script from a new origin can be expensive if it requires connection setup, downloads substantial JavaScript, runs on the main thread and then discovers several more third-party resources. Both cases still add to the request counter.
Distance can amplify connection and dependency-chain costs. A new connection or sequential request step can require one or more network round trips before useful response data arrives. A round trip between a visitor in São Paulo and infrastructure in Europe takes longer than a nearby regional path. A page that looks fine close to its infrastructure can therefore accumulate more delay for a distant audience when it depends on additional origins or long chains. The guide to why website speed varies by location covers the regional effect in more detail.
Why does request depth matter more than request count?
The browser can fetch many resources concurrently, but it cannot fetch a resource it has not discovered yet. A chain forms whenever one response, parse step or script execution has to happen before the browser learns about the next request.
HTML → stylesheet → imported stylesheet → web font
That is a sequential path. The font cannot be discovered from the second stylesheet until the earlier resources have been fetched and processed.
Other common examples include:
- A tag manager loads, runs and injects an analytics script, which then loads configuration and another library.
- A JavaScript framework downloads its entry bundle, executes it, calls an API and only then learns which hero image should be requested.
- An above-the-fold resource is referenced indirectly through another stylesheet or script rather than being discoverable from the initial HTML.
Each link in a dependency chain can add network latency plus whatever processing has to happen before the next link becomes discoverable.
Picture two pages with 80 requests each. On one, most of the requests are discovered directly from the HTML and can start early. On the other, the main content sits at the end of a five-step chain. The second page can display its important content later even though both pages have the same request count.
This is why the resource behind Largest Contentful Paint deserves special attention. If a hero image or other main-content resource is discovered late because it is inserted by JavaScript, referenced indirectly by CSS, or incorrectly lazy-loaded above the fold, its start time is pushed later.
Making that resource discoverable earlier can matter more than removing many unrelated background requests.
Which requests deserve the most attention?
A high count is a reason to look closer, not a diagnosis. These requests are more likely to affect the visible load:
Requests to new third-party origins
Analytics, A/B testing tools, chat widgets, consent platforms, ad scripts, font services and review embeds can introduce additional DNS work, connection setup and JavaScript. They also depend on infrastructure and geography you do not control.
Render-blocking resources
Stylesheets and blocking scripts that have to complete before rendering place their latency directly on the path to visible content. Deferring non-critical scripts and keeping the critical render path short usually matters more than reducing an arbitrary request total.
Late-discovered critical resources
Hero images, primary fonts and above-the-fold resources are especially costly when the browser can discover them only after downloading or executing something else.
Requests that add substantial JavaScript
JavaScript bytes have a second cost after transfer: the browser must parse, compile and execute them. That work competes with rendering and interaction on the main thread, particularly under slower CPU conditions.
Other requests can be comparatively harmless. Below-the-fold images may load only when they approach the viewport, background prefetches may occur after the page is already usable, and cached resources on an existing connection can add little visible delay.
Removing those requests can lower a counter without materially improving what a visitor experiences.
When can adding requests make a page faster?
The request total can increase while the user experience improves.
Code splitting
Breaking a very large JavaScript bundle into a small entry chunk plus route-level or feature-level chunks adds requests, but it can reduce how much code needs to be transferred and executed before the current page becomes usable.
Lazy loading below-the-fold media
Offscreen media can be deferred until it is closer to the viewport, reducing competition with resources needed for the first screen. Some deferred resources may therefore be requested later rather than during the initial critical load.
Cache granularity
Separating stable dependencies from frequently changing application code can let returning visitors reuse unchanged cached files. A single giant bundle may be invalidated by a comparatively small deployment.
Not inlining everything
A small amount of truly critical CSS can be useful inline because it avoids a blocking fetch. Inlining large stylesheets, images or other assets can instead bloat the HTML response and prevent those resources from being cached independently.
This does not mean request count is irrelevant. Hundreds of tiny production modules still create overhead, and very small files can lose some compression efficiency. The practical goal is deliberate bundling and splitting rather than a race toward either one file or a thousand.
How to read the request count in a Latixo test
A Latixo website speed test loads the submitted page in a real Chromium browser on a Browser Node in the selected region. The result shows a Requests figure alongside page weight, total load time, TTFB, HTTP status, negotiated protocol, content type, test node, final screenshot and Loading Replay.
What gets counted
The Requests value is the number of network requests Chromium issues during the measured run, including the main document request.
The Browser Node continues briefly after navigation while it waits for network activity to settle and prepares the capture. Requests triggered after the document's load event can therefore contribute to the final request total even though they did not delay the load event itself.
Each run uses a new browser context
Latixo creates a new Chromium browser context for each test. That isolates a run from browser storage belonging to an earlier visit and makes the test closer to a first-visit lab load than a returning visitor with previously cached page resources.
Real returning visitors can experience different transfer behavior because their browser may already have reusable cached assets.
The number can change between runs and regions
Ads, experiments, consent state, third-party services and geo-specific behavior can change which requests fire. The same URL tested from Virginia and Nuremberg can legitimately produce different request totals when the page or its third parties respond differently by region.
Run the same test more than once before treating a small difference as meaningful.
The request recommendation is a heuristic
In the current Latixo production logic, a page with 50 or fewer recorded requests passes the request count check as lean. Above 50, Latixo suggests making fewer HTTP requests; above 90, the request-count recommendation is flagged more strongly.
These values are diagnostic heuristics, not web standards. A page above them can still load quickly, while a page below them can still be slow because of server response time, blocking resources, dependency chains or expensive JavaScript.
Read requests together with the other measurements
A high request count with modest page weight and a quick load time can indicate many small, inexpensive requests. A high count combined with heavy page weight gives you more reason to inspect large images and script bundles first.
A modest request count with a long load time points elsewhere: server response, dependency chains, rendering work or another bottleneck may dominate. See what counts as a good TTFB when the initial response is the suspicious part.
The final screenshot and Loading Replay add visual context: they help show whether network activity corresponds to content a visitor actually sees.
Compare Desktop and Mobile
Latixo's simulated Mobile profile uses a 390 × 844 viewport at DPR 3, 4× CPU slowdown and network throttling of 1.6 Mbps down, 750 Kbps up and 150 ms latency.
Long dependency chains, large transfers and heavy JavaScript can become more visible under those constrained conditions than under the Desktop profile.
Know what the general test does not show
The general Website Speed Test reports the request total, but it is not a complete public per-request waterfall. When you need to trace a precise chain or inspect individual requests, use the Network panel in Chrome DevTools or another dedicated waterfall tool.
For Shopify storefronts, the Latixo Shopify Speed Test provides additional resource diagnostics for the measured storefront load, including resource classification and largest or slowest observed resources.
The website speed test metrics methodology explains how Latixo's main performance fields should be interpreted.
Where to start if the count is high
When a test flags a high request count, identify what the requests are before deleting them.
Group requests by origin
Look for third-party origins that account for a meaningful share of requests, JavaScript or connection setup. Remove tags that are no longer required. For those that remain, decide whether they really need to load before the page is usable.
Find the dependency chains
Avoid unnecessary CSS @import chains. Make important above-the-fold resources
discoverable early. Use preload selectively for resources that are genuinely critical and otherwise
discovered too late, and reserve preconnect for the small number of cross-origin
connections that are important enough to justify opening early.
Reduce unnecessary cross-origin work
Where operationally appropriate, serving fonts or small dependencies from infrastructure you control can avoid an additional third-party origin and give you more direct control over caching and delivery.
Defer what is not required for first render
Use appropriate loading strategies for non-critical scripts and consider delaying chat widgets, embeds or similar features until after the initial render or user interaction where that fits the product experience.
Re-test like for like
Use the same URL, Browser Node and Desktop or Mobile profile across repeated runs. Compare request count with total load time, page weight, TTFB, screenshot and Loading Replay rather than judging the request number in isolation.
A lower count that changes nothing visible may not be a meaningful improvement. A slightly higher count that makes important content appear earlier can be the better outcome.
Request count is a clue, not a performance verdict
More HTTP requests can make a website slower, but only through specific mechanisms: connection setup, sequential dependencies, bandwidth competition, extra JavaScript, transferred bytes and server work.
If you count requests without asking which of those costs you are actually paying, you can end up optimizing the counter rather than the page.
Test the actual page: run the same URL from the region and profile that matter to your audience, then read request count together with page weight, TTFB, total load time and the Loading Replay. Run a Latixo website speed test →